- Designing a Scalable & Fault-Tolerant Log Pipeline [Part 4]: Extract INFO from ERRORS
Flink, Nessie, Iceberg, and Trino as a long-term log archive and the SQL queries that turn months of error history into actionable signals.
15 min read - Designing a Scalable & Fault-Tolerant Log Pipeline [Part 2]: The Buffer Layer
Whether you actually need Kafka, what a buffer layer makes possible, and how to configure it correctly for log pipelines at scale.
7 min read - Designing a Scalable & Fault-Tolerant Log Pipeline [Part 3]: Storage & Analytics
Hot and cold storage are two separate decisions. VictoriaLogs, Loki, ClickHouse, and Iceberg/Parquet compared internals, benchmarks, and what I'm running.
11 min read - Designing a Scalable & Fault-Tolerant Log Pipeline [Part 1]: Agents and Forwarders
How to split responsibilities between log agents and forwarders, what each layer must handle, and three deployment patterns for log pipelines at scale.
4 min read -
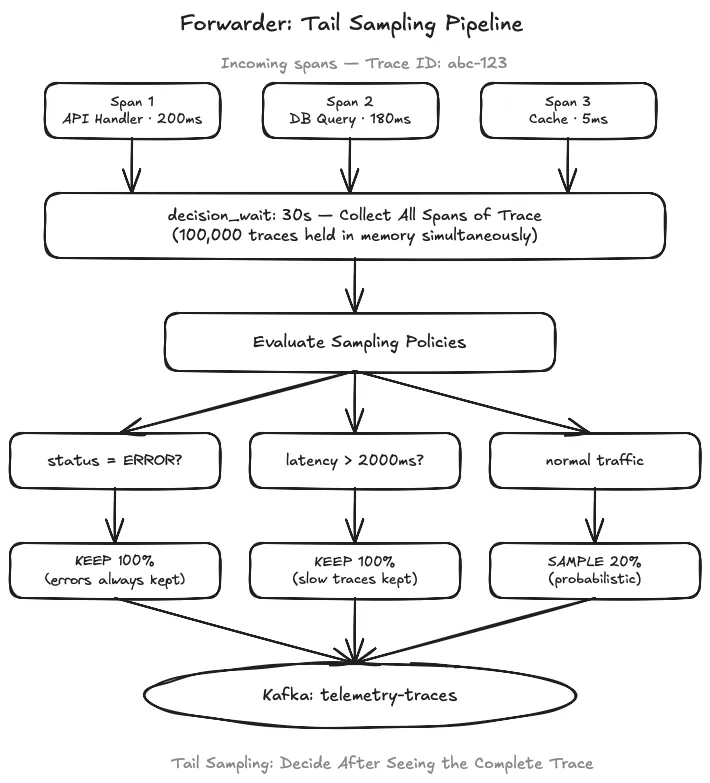 Designing a Telemetry Pipeline That Scales [Part 2]: Sampling, Kafka, Storage, and HA
How to make the pipeline durable at scale with tail sampling, Kafka buffering, VictoriaMetrics, Tempo, and production hardening.
14 min read